AutoDev LG Dev Log
Daily progress of a framework that builds apps automatically using only local LLMs
Current goal
E2E runs over time
Number of tests
Daily log
Sep 29 (Tue)
PASS! The local LLMs really built the app all the way through. Can't stop grinning.
A speed-tuning day. With MTP added to Flash-Next, generation even on a long 40k-token context went up from 20.3 → 31.7 tok/s (+56%).
- This fastest setup was adopted as v142, and taskboard's loop68 is running on it.
- If the results look good, we go back to fixing INVADERS with this setup.
Sep 28 (Mon)
It paid off...! This one run is why I keep going. The coffee tastes extra good today.
A day of rebuilding after WSL vanished. I also made a Windows-native version (v134/135), but llama-server was slow on long contexts, so we went back to WSL.
- On the rebuilt WSL, taskboard's loop67 PASSED (1h 19m). The rebuild worked.
- INVADERS' inv18 was NOT PASS. Test code generation came back
test_invalidon all three models, so it never reached coding. The Test stage is the current weak spot. - v141 added MTP (speculative decoding) as an experiment, to measure the speed.
Sep 27 (Sun)
A detour day. I found a YouTube video introducing Hermes Agent and jumped on it: “This is it!”
- ...But running it with local LLMs, it was basically useless. The dream lasted a few hours.
- Verdict: a whole day wasted. Meekly back to developing AutoDev LG.
- Meanwhile, while the human was cheating on them, the local LLMs quietly kept at it — 9 attempts, not a single complaint. Good bots.
Sep 26 (Sat)
3 PASSes in a row on taskboard!! Goal cleared - I actually shouted.
Sep 25 (Fri)
4 PASSes today! Can't stop laughing.
Sep 24 (Thu)
2 PASSes! All the struggle up to yesterday was for this day.
Sep 23 (Wed)
It paid off...! This one run is why I keep going. The coffee tastes extra good today.
Sep 22 (Tue)
In between runs, somehow a Mac mini got bought. "I'll need it to make iPhone apps someday," I told myself. ...So far, it hasn't been used once (lol).
Sep 21 (Mon)
2 PASSes! All the struggle up to yesterday was for this day.
Sep 20 (Sun)
Sep 19 (Sat)
Sep 18 (Fri)
Sep 17 (Thu)
Sep 16 (Wed)
Sep 14 (Mon)
The first PASS ever!! The local LLMs really built an app from start to finish...! I keep rereading the logs.
The early days
Jul 30, 2026 (Thu)
Where it all began. "I want to try vibe coding with a local LLM!" — except I had neither the skills nor the time to write code myself. So here was the brilliant plan.
- Pay just $2 to DeepSeek, famous for being cheap, and have it build an app that builds programs that make a local LLM do simple command-line jobs. Have an AI build an app that puts another AI to work. (Confusing, I know.)
- My only GPU back then was a single RTX 5070 (12GB). Compared with today's five-card rig, it was a light start.
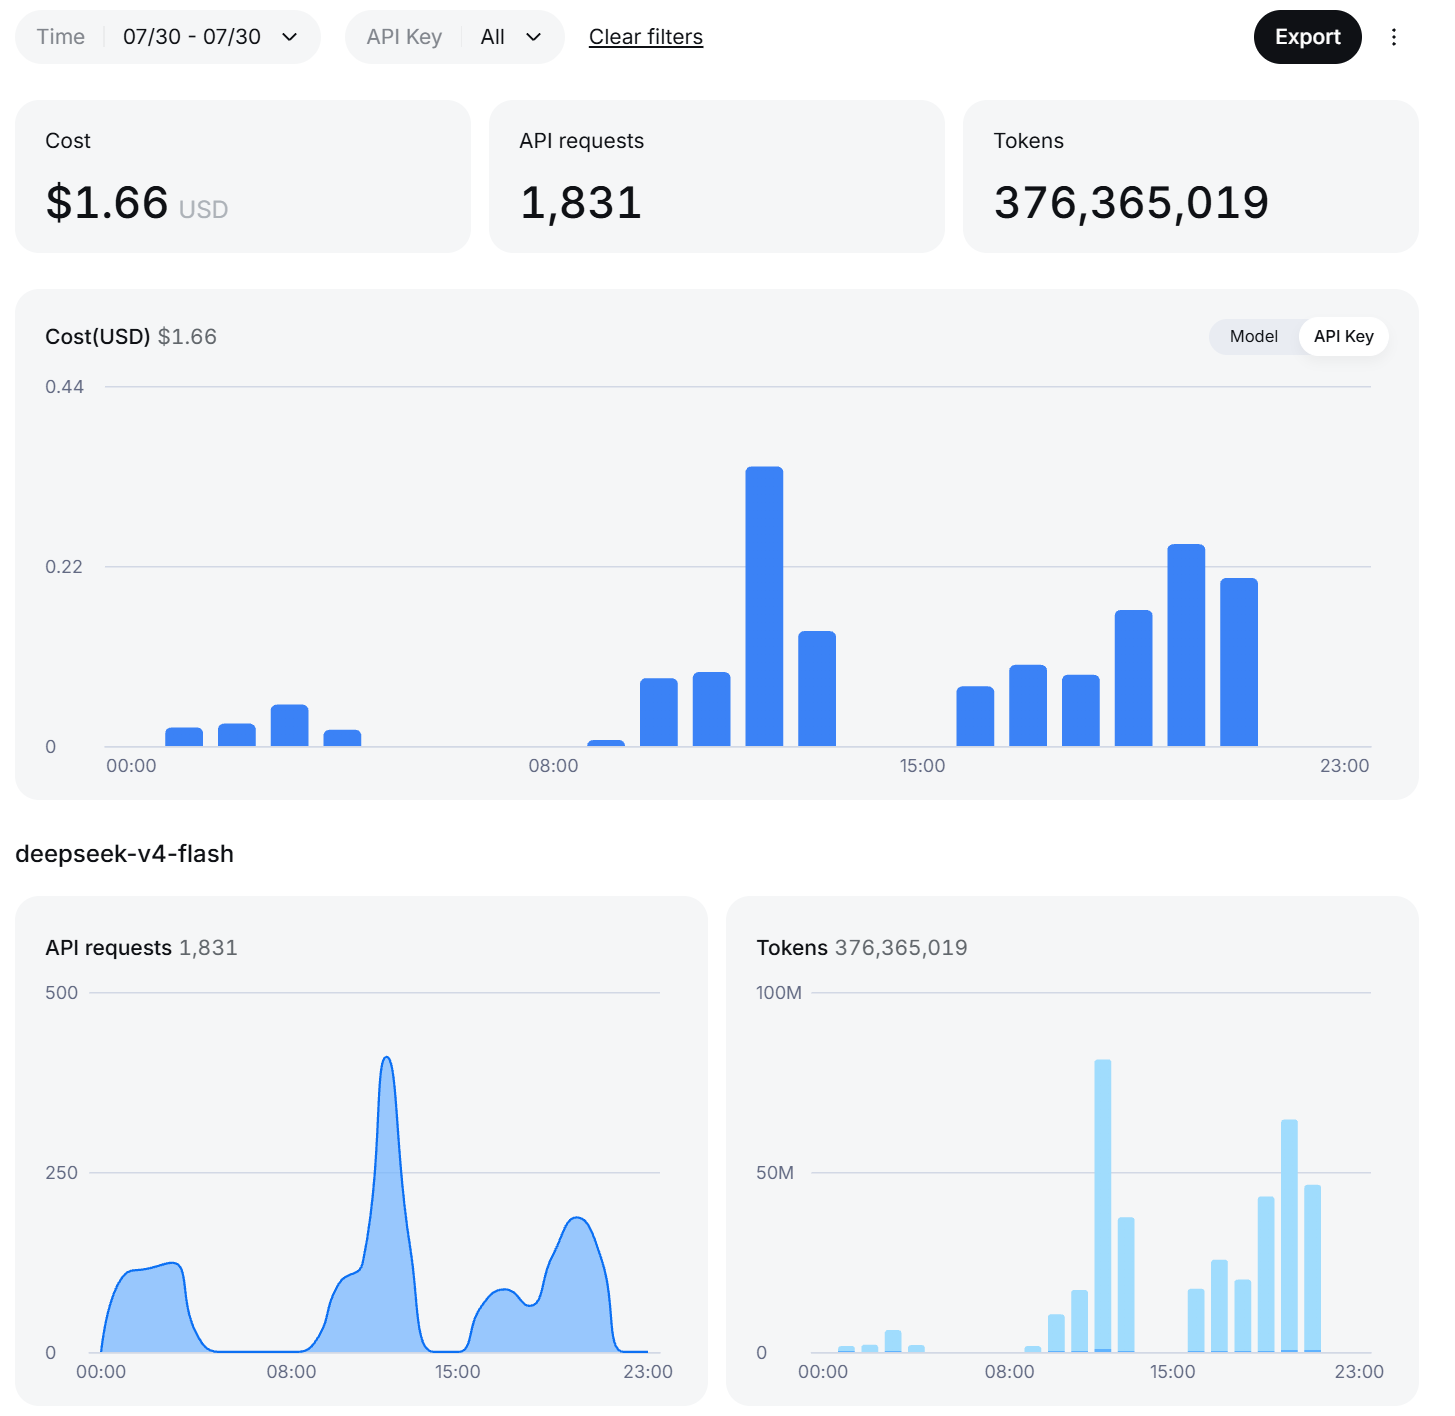
- The result: 1,831 API requests and 376,365,019 tokens (about 380 million) in one day. Just before noon it was calling DeepSeek 400 times an hour. And the bill was still only $1.66. Cheap. Scary cheap.
- But even once something worked, every new feature made DeepSeek wipe out the existing ones (a classic regression). Fix it, it's gone, fix it, it's gone — forever.
- I got bored in one day. ...Yet this "adding a feature breaks the old ones" problem is exactly why AutoDev LG later became so obsessed with building under the protection of tests.
Aug 27, 2026 (Thu)
GPU upgrade. The official reason: "smoother gaming." Swapped the RTX 5070 for an RTX 5070 Ti, bought on a flea-market app for ¥169,800! (Around here I started to feel I'd lost it a little.)
- And on the same day, unable to resist the urge to "run a bigger LLM locally," I also bought an RTX 5060 Ti 16GB.
- Two GPUs in one day. From here on, the GPUs multiply like mushrooms after rain.
Sep 03, 2026 (Thu)
More GPUs. Two more RTX 5060 Ti 16GB cards. (I've lost it.)
- That makes four GPUs. The more VRAM you have, the bigger the models you want to try. This is the entrance to the rabbit hole.
Sep 04, 2026 (Fri)
More GPUs (the very next day). Yesterday's two weren't enough, so one more RTX 5060 Ti 16GB. (Completely out of my mind.)
- One 5070 Ti + four 5060 Ti = five in total. But at this point there's no PC that can hold five cards yet. I did things in the wrong order.
Sep 06, 2026 (Sun)
The turning point. While I was grumbling, "No matter how many GPUs I add, it's still DeepSeek writing the code...," an email or something told me ChatGPT Plus was free for a month. Signed up on the spot.
- To get revenge for the 7/30 regression hell, this time I teamed up with a smarter partner.
- Talking things over with ChatGPT, the idea of today's AutoDev LG slowly started to take shape. The smart AI builds "the system that builds," and the local LLMs at home build the actual apps — that division of labor came into view that day.
Sep 08, 2026 (Tue)
New PC case, and the 80GB fortress is complete. To fit five GPUs, I switched to the big LIAN LI O11D EVO XL case. When the box arrived, I was shocked at how huge it was.
- The motherboard stays the same ASRock B760 Pro RS/D4 WiFi I already had: server boards are out of reach, and this PC is also for gaming.
- Of course there aren't enough PCIe slots. So, with an assortment of riser cables — knowing full well the bandwidth gets narrower — I crammed all five GPUs in. An 80GB VRAM setup, complete.
- From here began the days of having ChatGPT build AutoDev LG and testing it with local LLMs.
- ...But ChatGPT quickly hit its usage limit. The same day, I signed up for Claude Pro too. Run, fail, fix, run again — the long journey begins.